
8.0
热点
AI SCORE
技术实践2026-09-29 02:24
生产级 AI 不能只靠模型版本管理
Stack Overflow Blog#MLOps#AI运维#最佳实践
Editor brief · 编辑速览
Stack Overflow 博客指出生产 AI 需完整 MLOps 流程,涵盖评估、部署与回滚,版本号不够用。
Imagine a documentation assistant that starts timing out after a routine retrieval change. The model is the same. The service is healthy. Every deployment check passed. But the retriever now sends more context, generation takes longer, and requests pile up behind a busy inference server. Reverting the application container does not help because the retrieval configuration lives elsewhere.
This is a hypothetical incident, but it exposes a useful design question: what, exactly, did the team deploy?
For an AI application, a model version is only part of the answer. Inputs, preprocessing, prompts, retrieval, tool contracts, and serving settings can change behavior independently. Reliable AI infrastructure needs a release boundary around the components that must work together. MLOps then becomes the workflow for testing that release, observing it under real traffic, and replacing it safely.
The practical starting point is not a bigger platform. It is a versioned release manifest, a meaningful evaluation gate, and a rollback path that has actually been tested.
Traditional ML systems already have this problem: a classifier trained with one feature transformation can behave incorrectly when production applies another. Google's MLOps guidance describes training-serving skew and the need for data and model validation within automated pipelines. Generative applications extend the set of dependencies; they do not remove the need to manage them. [1]
For a retrieval-augmented generation application, I would begin with a small manifest like this. The values below are illustrative identifiers, not a runnable platform specification.
release_id: docs-assistant-r17
app_revision: git-8f2a1c
model_revision: model-snapshot-42
prompt_revision: support-v7
retrieval:
  index_revision: docs-index-2026-09-01
  embedding_revision: embed-v3
  pipeline_revision: chunk-and-rank-v4
runtime_revision: serving-config-v6
evaluation_suite: support-regression-v12
previous_release: docs-assistant-r16
Each reference should resolve to retained, inspectable configuration or artifacts. The runtime revision should cover settings that affect execution, such as token limits, batching, timeouts, and resource placement. If the application calls tools, version the schemas and adapters too. Store references to secrets, never secret values, in the manifest.
A manifest is not a promise of bit-for-bit reproducibility. External services change; generation can remain nondeterministic; a provider may not offer immutable model snapshots. Record those limits instead of disguising a floating alias as a fixed version. Where data changes continuously, record the ingestion watermark and index configuration so an incident can be investigated even when replay is imperfect.
This does not require copying the entire environment for every release. It requires knowing which combination was tested, and resolving that combination consistently when a request begins. Updating four configuration stores one after another is not an atomic release.
Figure 1. Test and promote the release as a unit. Production failures feed the next evaluation suite.
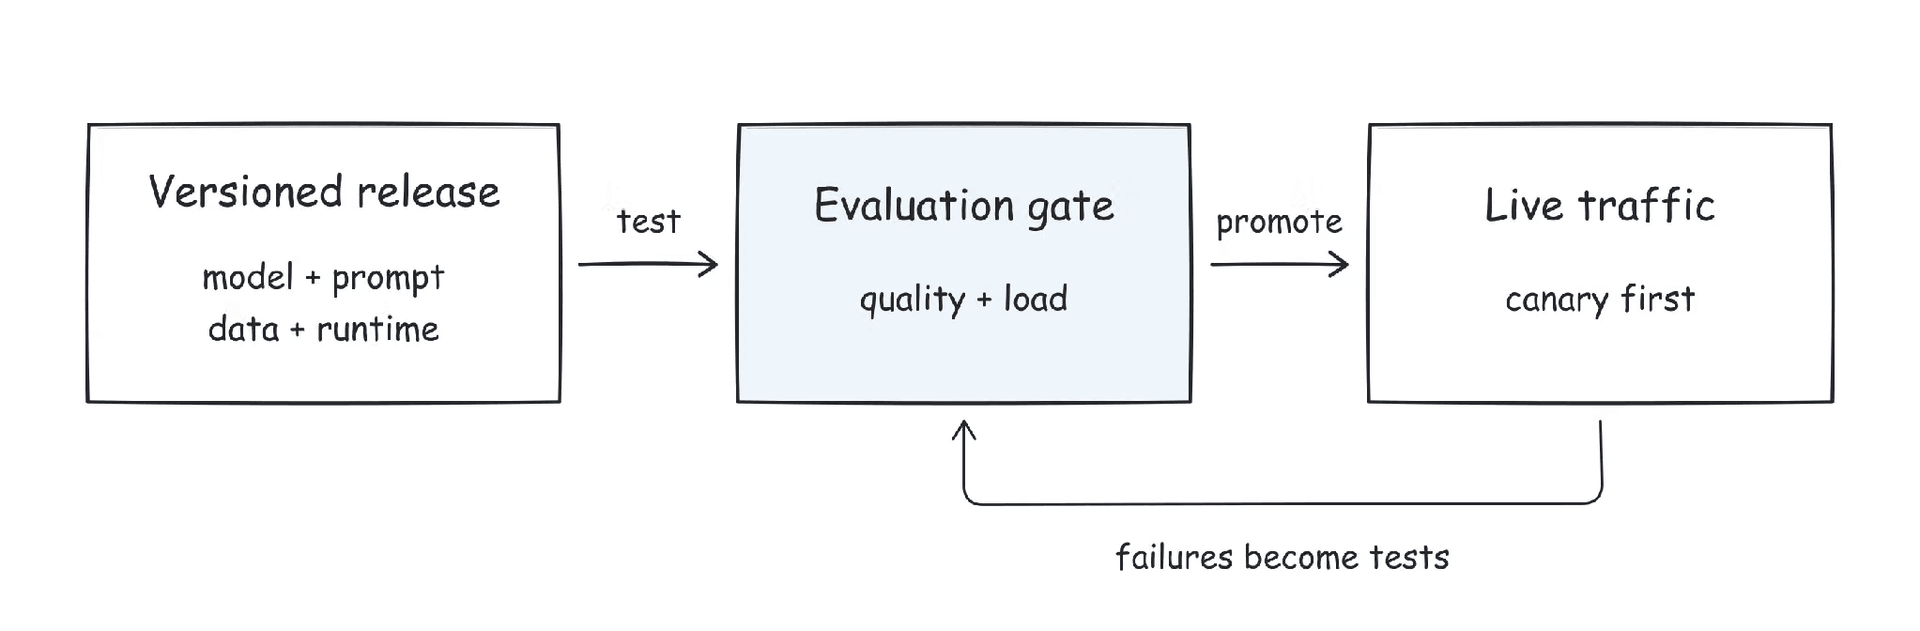
A service can return HTTP 200 and still fail the user. For a documentation assistant, a useful answer might need to cite an accessible source, reflect the correct product version, and decline to invent instructions when evidence is missing. Those are different checks from endpoint availability.
Start with a compact, versioned dataset built around the tasks the feature is meant to complete. Include ordinary questions, previously observed failures, ambiguous requests, missing evidence, and attempts to cross authorization boundaries. Keep a held-out set so repeated prompt tuning does not turn the entire suite into a training target.
Use deterministic checks where possible: schema validity, allowed tool arguments, citation identifiers, and permission enforcement. For semantic judgments, define a rubric and compare automated scores with human review. A model-based judge can help prioritize review, but its output is not ground truth. Pin its configuration and investigate disagreements rather than averaging them away.
The gate should evaluate the full path, not just call the model with a prepared prompt. In the opening example, a model-only test would miss the change in retrieved context. Run the same release through retrieval, generation, and output validation, then inspect results by meaningful slices: long inputs, languages, product versions, and requests with sparse evidence.
Choose acceptance criteria before looking at the candidate. A practical policy might block a release on any observed access-control violation, require reviewed evidence that important task slices have not regressed beyond a chosen tolerance, and require the latency and cost budgets to hold under a representative workload. Passing a finite suite does not prove the absence of security flaws or rare failures.
A failed gate should produce a debugging artifact: the candidate and baseline release IDs, dataset revision, failed cases, and relevant traces. A red build that says only "quality decreased" leaves the next engineer with another research project.
Requests per second alone is a weak description of an LLM workload. A short question with a short answer and a long document with a long answer can impose very different demands. Test distributions of input length, output length, concurrency, and arrival bursts. Include both warm and cold cache behavior.
For streaming responses, separate time to first token from the pace of subsequent tokens and total completion time. Queue time matters too: a server can generate tokens quickly after admission while users spend most of their time waiting. vLLM's metrics documentation exposes these distinct measurements, alongside queue-depth gauges and token counters. These server-side measurements do not replace client-visible latency across retrieval, networking, and rendering. [2]
Start with end-to-end traces, then inspect retrieval, reranking, queueing, prefill, decoding, and downstream calls where the serving stack exposes them. Do not add the p95 of each stage and call it the end-to-end p95; those percentiles may describe different requests. Use per-request timing to identify where slow requests spend their time.
Batching illustrates the tradeoff. Waiting to assemble work can improve throughput, yet extend user-visible delay. NVIDIA's Triton documentation makes this tradeoff explicit through configurable queue delay for dynamic batching. That mechanism is not identical to an autoregressive server's continuous batching, but the operational lesson carries over: benchmark the scheduler you actually run. [3]
GPU utilization is a diagnostic signal, not the product objective. Decide what the user must experience, then measure how much capacity it takes to meet that requirement. Bound queues, propagate deadlines, and cancel work when the client no longer needs it where the stack supports cancellation. Retries should respect the remaining deadline and an explicit retry budget; unlimited retries can add load to an already overloaded system.
Record release identity on traces and structured request events. Track quality signals, latency distributions, errors, token usage, and fallback rates together. Keep high-cardinality identifiers in traces or logs rather than turning every request or document into a metrics label. Record enough to diagnose behavior without logging raw prompts and retrieved content by default; access controls, redaction, sampling, and retention limits matter.
A cheaper request is not necessarily a cheaper completed task. If a low-cost candidate triggers more retries or human escalation, its apparent saving may disappear. For a fixed measurement window, calculate cost per successful task as the attributable serving and supporting costs divided by tasks meeting a defined success criterion. Count failed attempts in the numerator. If reliable success labels are unavailable, report the proxy explicitly instead of calling it task success.
Compare like with like. Cache hit rate, output length, traffic mix, and quality all affect the result. A release that looks cheaper because it silently truncates answers should fail evaluation, not win a cost comparison. The goal is a useful operating envelope: which workloads meet the quality and latency requirements, at what cost, and with how much headroom?
Keep the current release available while exposing a candidate to a bounded share of traffic. A canary is useful because it limits exposure and creates a comparison, not because a particular percentage is universally safe. Google's SRE guidance emphasizes comparing canary and control signals before expanding a rollout. [4]
Figure 2. Retain a known-good release so rollback can move new requests away from the candidate.
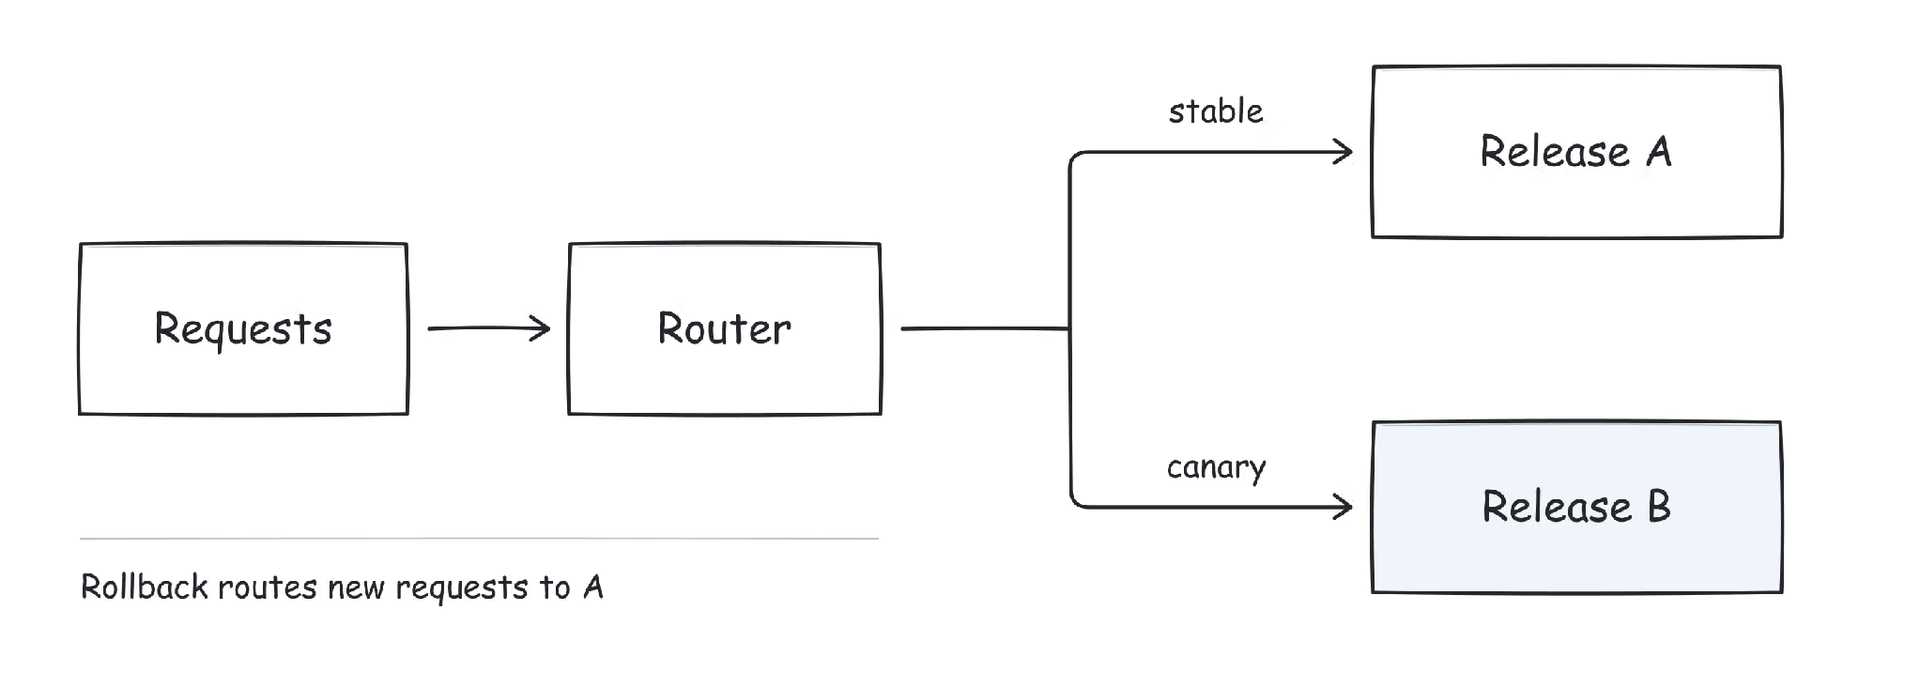
Choose assignment deliberately. Randomizing each request may be fine for independent tasks; a conversation may need stable assignment so its behavior does not change midway. Confirm that the canary exercises the workload slices that matter. A quiet canary is not evidence about peak load, and too few completed tasks cannot establish a reliable quality comparison.
Check absolute service objectives as well as candidate-versus-control differences: a shared failing dependency can degrade both. Separate rapid safety signals from slower product signals. Timeouts or a confirmed permission violation can justify stopping immediately. Quality labels and escalation outcomes may arrive later, so promotion may need to wait. Define the owner, stop conditions, minimum observation requirements, and recovery procedure before starting the rollout.
Rollback must restore compatible dependencies, not just older model weights. If the candidate overwrites the retrieval index in place, routing back to an old application image may still leave it reading the new index. Retain compatible index versions or design a reversible migration. Historical snapshots must still honor current access revocations and deletion requirements. Version or invalidate relevant caches so an old route does not serve results produced under the candidate's assumptions.
Routing only affects requests that have not yet been assigned. In-flight generations need an explicit drain or cancellation policy. Tool side effects need separate protection: sending an email or updating a record cannot be undone by switching model versions. Use idempotency and approval boundaries appropriate to those actions, and do not let shadow traffic execute real side effects.
After an incident, add the failure to the evaluation suite with its expected behavior and context. That is the connection between operations and the next release. But production feedback is selective: complaints overrepresent some users, clicks are not necessarily correctness, and missing labels can hide unsuccessful sessions.
For predictive models, input drift can trigger investigation; it does not by itself prove that accuracy has fallen or that retraining will help. For generative applications, a prompt or retrieval change can require a new release even when there is no training job. In both cases, promotion should depend on evidence about the resulting system.
Assign ownership at the interfaces. The application team defines acceptable task behavior. The platform team makes release resolution, deployment, telemetry, and recovery dependable. Data owners maintain freshness and access policies. Decide who can stop a rollout; an alert without someone empowered to act is incomplete infrastructure.
The smallest useful implementation can live in an existing repository: a release manifest, an evaluation job, a representative load test, release-aware traces, and a rehearsed switch back to the previous version. Add more platform machinery when repeated operational pain justifies it.
Before the next launch, ask one question: can the on-call engineer identify the complete release behind a bad answer and restore a compatible known-good version? If not, improve that path before making deployment faster.
[1] Google Cloud. MLOps continuous delivery and automation pipelines in machine learning
[2] vLLM. Production metrics
[3] NVIDIA Triton Inference Server. Batchers
[4] Google SRE Workbook. Canarying releases